Software Engineer · AWS OpenSearch Rust · Java · Lucene · Parquet

Shailesh Kumar Singh

I build the parts of databases
that mergeindexaggregatescale data
and stay fast at 10 TB.

scroll
7 GB → <500 MB peak merge memory✦ up to 300× faster nested aggregations✦ 14 merged PRs to OpenSearch✦ Berlin Buzzwords 2026 speaker✦ ICPC All-India Rank 188✦
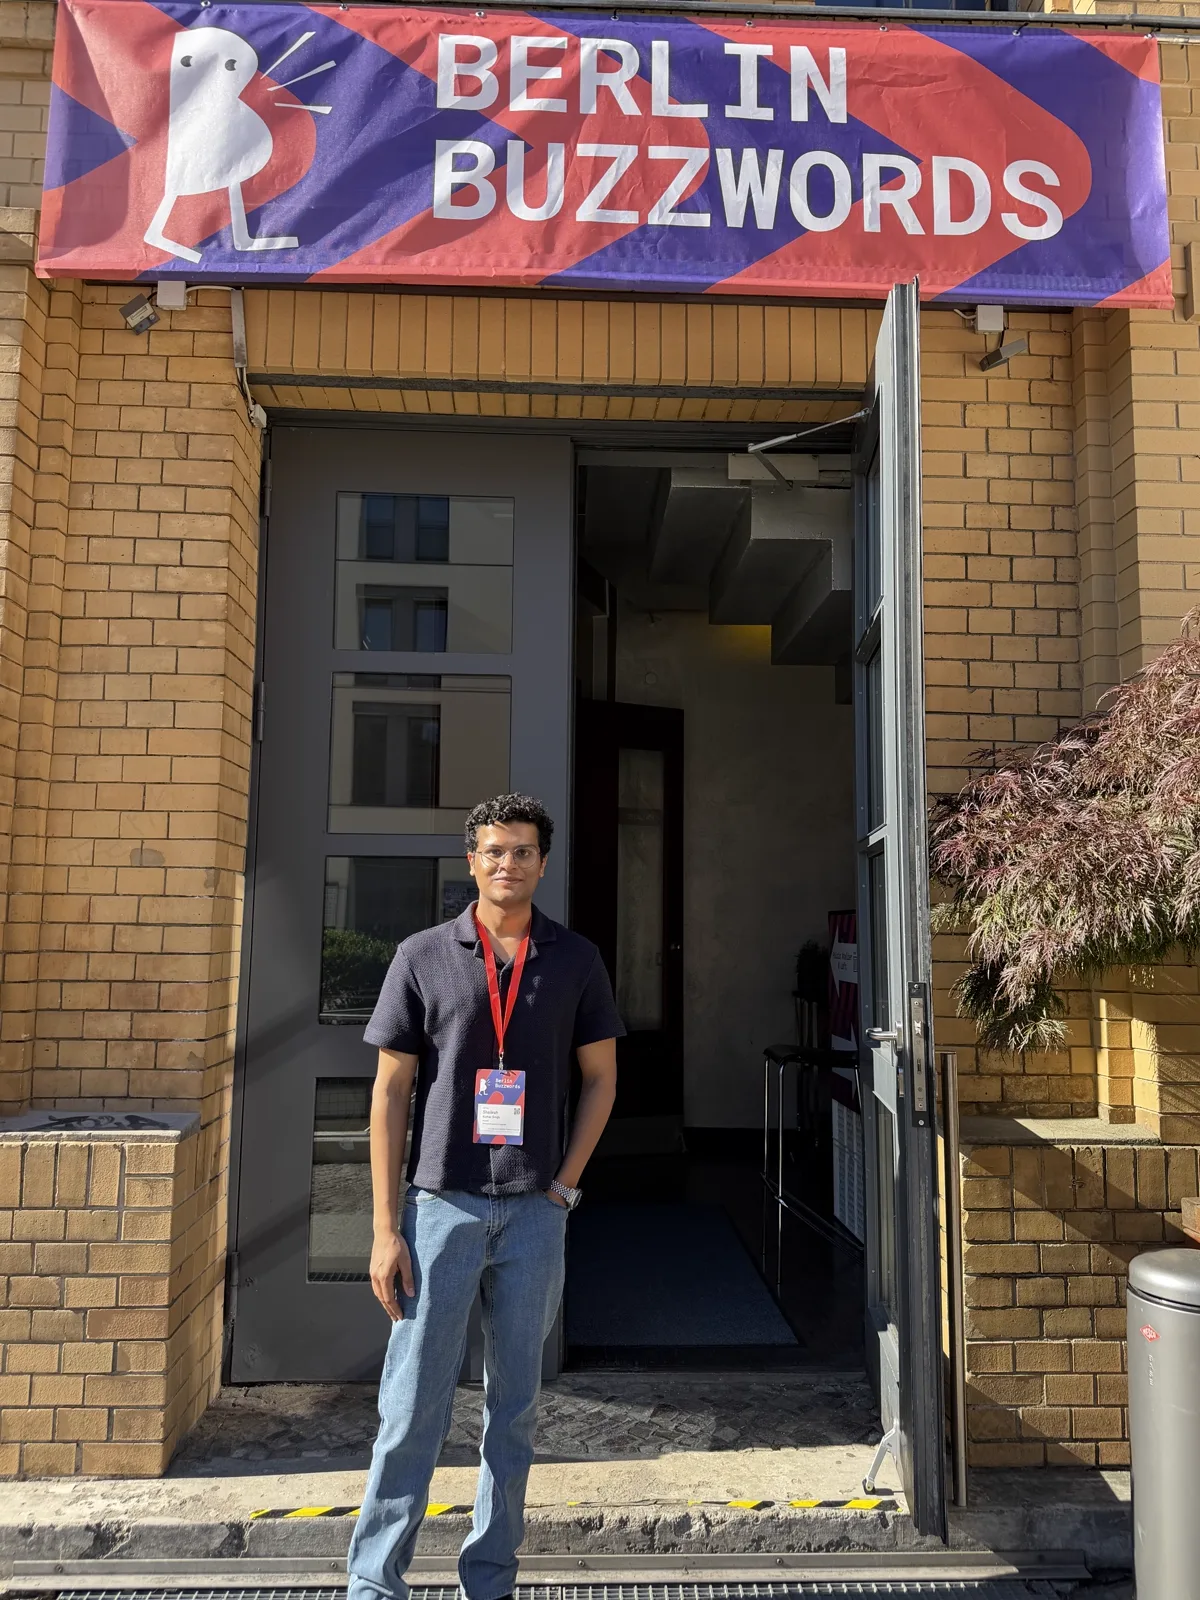
Shailesh outside the Berlin Buzzwords venue in Berlin
Berlin · 2026

00 / hello

I'm Shailesh. I work on the indexing engine behind Amazon OpenSearch: the code that writes, merges and pre-aggregates data so a query over billions of rows comes back in milliseconds.

Before that: competitive programming (ICPC AIR 188), TA for Design & Analysis of Algorithms at BITS Pilani, and shipping features to Amazon delivery customers as an intern. On weekends I turn randomized algorithms into animated videos.

Engineerbuilding search & storage at AWS OpenSearch
Speakeron stage at Berlin Buzzwords 2026
Creatoranimating algorithms on CoinFlip Labs

01 / work

Case files

Two problems from AWS OpenSearch Indexing, both open source. The demos run live in your browser.

A
JavaLuceneOpen source

Star-Tree: answer the query before it's asked

A Star-Tree pre-computes aggregations at index time, so a query walks a few nodes instead of scanning every document. I added nested group-by aggregations (Terms, Range, Date-Histogram) and unsigned-long support, and found 5 existing correctness bugs along the way.

  • 5–300× faster multi-level analytics
  • 5 pre-existing bugs uncovered, 2 fixed upstream
  • Mentored an intern: index upgrades 24.8 h → 6 min

↳ build a query and race it

star_tree.query · demo data
doc scan
0
star-tree
0
B
RustArrowRayonTokioParquet

A merge engine that never runs out of memory

OpenSearch's new Parquet storage merges segments with an engine I built in Rust: a three-tier k-way cascade that moves whole batches zero-copy when it can, parallel column encoding, and a rate-limited async writer. Backpressure keeps memory flat, so 10 GB and 10 TB merge in the same few hundred MB.

  • ~14× lower peak memory: 7 GB → <500 MB
  • Zero-copy whole batches when sort ranges don't overlap
  • Never starves indexing: bounded queues and rate-limited writes
↳ read the pull request ↗
parquet_merge_stream.rs · live overlap
drain0%
zero-copy0%
binary search0%
___row_id0
peak memory320 MB

02 / on stage

Berlin, Germany52.52° N · 13.40° E

Berlin Buzzwords 2026

Constant-Time Aggregations with Star-Tree in OpenSearch

Speaker profile ↗

move your cursor ↔

03 / side quest

CoinFlip Labs

My YouTube channel, where randomness is the superpower. Every number on screen comes from a real experiment I wrote first, then animated in Manim and Blender.

Visit the channel ↗
heads0
tails0
heads %-
🎯 Challenge: flip 2 heads in a row
click the coin

truly random · uses your browser's crypto RNG

04 / journey

How I got here

05 / toolbox

Grab a skill

They have gravity. Throw them around.

06 / contact

Let's build
something fast.